
Microsoft Perform Data Engineering on Microsoft Azure HDInsight - 070-775무료 덤프문제 풀어보기
HOTSPOT
You install the Microsoft Hive ODBC Driver on a computer that runs Windows 10 and has the 64-bit version of Microsoft Office 2016 installed.
You deploy a new Apache Interactive Hive cluster in Azure HDInsight. The cluster is hosted at myHDICluster.azurehdinsight.net and contains a Hive table name hivesampletable that has 200,000 rows.
You plan to use HiveQL exclusively for the queries. The queries will return from 6,000 to 10,000 rows 90 percent of the time.
You need to configure a data source to ensure that you can use Microsoft Excel to access the dat a. The solution must ensure that the Hive queries execute as quickly as possible.
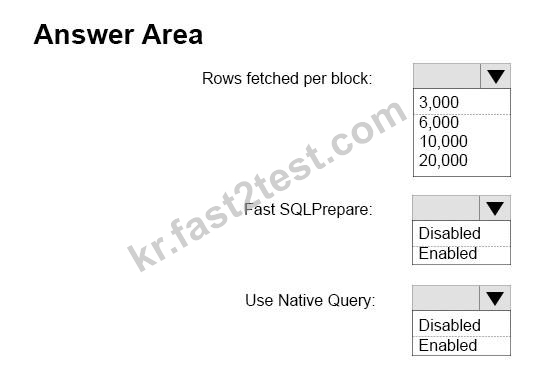
How should you configure the Advanced Options from the Microsoft Hive ODBC Driver DSN Setup dialog box? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
You install the Microsoft Hive ODBC Driver on a computer that runs Windows 10 and has the 64-bit version of Microsoft Office 2016 installed.
You deploy a new Apache Interactive Hive cluster in Azure HDInsight. The cluster is hosted at myHDICluster.azurehdinsight.net and contains a Hive table name hivesampletable that has 200,000 rows.
You plan to use HiveQL exclusively for the queries. The queries will return from 6,000 to 10,000 rows 90 percent of the time.
You need to configure a data source to ensure that you can use Microsoft Excel to access the dat a. The solution must ensure that the Hive queries execute as quickly as possible.
How should you configure the Advanced Options from the Microsoft Hive ODBC Driver DSN Setup dialog box? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
정답:

References: https://docs.microsoft.com/en-us/azure/hdinsight/hdinsight-connect-excel-hive-odbc- driver
DRAG DROP
You have an Apache HBase cluster in Azure HDInsight. The cluster has a table named sales that contains a column family named customerfamily.
You need to add a new column family named customeraddr to the sales table.
How should you complete the command? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.

You have an Apache HBase cluster in Azure HDInsight. The cluster has a table named sales that contains a column family named customerfamily.
You need to add a new column family named customeraddr to the sales table.
How should you complete the command? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
정답:

Hbase > disable 'sales'
Hbase > alter 'sales'
'customerfamily',
{NAME => 'customeraddr',
IN_MEMORY => false},
Hbase > enable 'sales'
You have an Azure HDlnsight cluster.
You need to build a solution to ingest real-time streaming data into nonrelational distributed database.
What should you use to build the solution?
You need to build a solution to ingest real-time streaming data into nonrelational distributed database.
What should you use to build the solution?
정답: C
You create a Linux-based Azure HDInsight cluster by using the Azure portal.
You plan to use Microsoft Power Query for Excel to debug a job failure.
You need to identify all of the components that failed for the head node.
Which component contains the log files?
You plan to use Microsoft Power Query for Excel to debug a job failure.
You need to identify all of the components that failed for the head node.
Which component contains the log files?
정답: D
설명: (Fast2test 회원만 볼 수 있음)
Note: This question is part of a series of questions that use the same or similar answer choices. An answer choice may be correct for more than one question in the series. Each question is independent of the other questions in this series. Information and details provided in a question apply only to that question.
You are implementing a batch processing solution by using Azure HDInsight.
You have a workflow that retrieves data by using a U-SQL query.
You need to provide the ability to query and combine data from multiple data sources.
What should you do?
You are implementing a batch processing solution by using Azure HDInsight.
You have a workflow that retrieves data by using a U-SQL query.
You need to provide the ability to query and combine data from multiple data sources.
What should you do?
정답: D
설명: (Fast2test 회원만 볼 수 있음)
Note: This question is part of a series of questions that use the same or similar answer choices. An answer choice may be correct for more than one question in the series. Each question is independent of the other questions in this series. Information and details provided in a question apply only to that question.
You need to deploy an HDInsight cluster that will provide in-memory processing, interactive queries, and micro-batch stream processing. The cluster has the following requirements:
Uses Azure Data Lake Store as the primary storage
Can be used by HDInsight applications
What should you do?
You need to deploy an HDInsight cluster that will provide in-memory processing, interactive queries, and micro-batch stream processing. The cluster has the following requirements:
Uses Azure Data Lake Store as the primary storage
Can be used by HDInsight applications
What should you do?
정답: F
설명: (Fast2test 회원만 볼 수 있음)
Note: This question is part of a series of questions that use the same scenario. For your convenience, the scenario is repeated in each question. Each question presents a different goal and answer choices, but the text of the scenario is exactly the same in each question in this series.
You have an initial dataset that contains the crime data from major cities.
You plan to build training models from the training dat
a. You plan to automate the process of adding more data to the training models and to constantly tune the models by using the additional data, including data that is collected in near real-time. The system will be used to analyze event data gathered from many different sources, such as Internet of Things (IoT) devices, live video surveillance, and traffic activities, and to generate predictions of an increased crime risk at a particular time and place.
You have an incoming data stream from Twitter and an incoming data stream from Facebook, which are event-based only, rather than time-based. You also have a time interval stream every 10 seconds.
The data is in a key/value pair format. The value field represents a number that defines how many times a hashtag occurs within a Facebook post, or how many times a Tweet that contains a specific hashtag is retweeted.
You must use the appropriate data storage, stream analytics techniques, and Azure HDInsight cluster types for the various tasks associated to the processing pipeline.
You plan to consolidate all of the streams into a single timeline, even though none of the streams report events at the same interval.
You need to aggregate the data from the feeds to alight with the time interval stream. The result must be the sum of all the values for each key within a 10 second interval, with the keys being the hashtags.
Which function should you use?
You have an initial dataset that contains the crime data from major cities.
You plan to build training models from the training dat
a. You plan to automate the process of adding more data to the training models and to constantly tune the models by using the additional data, including data that is collected in near real-time. The system will be used to analyze event data gathered from many different sources, such as Internet of Things (IoT) devices, live video surveillance, and traffic activities, and to generate predictions of an increased crime risk at a particular time and place.
You have an incoming data stream from Twitter and an incoming data stream from Facebook, which are event-based only, rather than time-based. You also have a time interval stream every 10 seconds.
The data is in a key/value pair format. The value field represents a number that defines how many times a hashtag occurs within a Facebook post, or how many times a Tweet that contains a specific hashtag is retweeted.
You must use the appropriate data storage, stream analytics techniques, and Azure HDInsight cluster types for the various tasks associated to the processing pipeline.
You plan to consolidate all of the streams into a single timeline, even though none of the streams report events at the same interval.
You need to aggregate the data from the feeds to alight with the time interval stream. The result must be the sum of all the values for each key within a 10 second interval, with the keys being the hashtags.
Which function should you use?
정답: B