
Databricks Certified Data Engineer Professional - Databricks-Certified-Data-Engineer-Professional무료 덤프문제 풀어보기
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
정답: A
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is using Structured Streaming to read in transaction data from a bronze Delta table. It was discovered that the data has quality issues where sometimes the transaction value is negative, and when that occurs, the rows need to be routed to a separate quarantine table. They have low latency requirements for the good data since it is used by downstream systems, but the bad data will only be analyzed periodically and has no production dependencies. The quarantine job needs to be implemented so that it cannot affect the production processes that depend on the good data, and the cost of the job needs to be minimized. How should the quarantine process be implemented in order to satisfy these requirements?
정답: D
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is building a streaming data pipeline to ingest JSON files from cloud storage into a Delta Lake table. The pipeline must process files incrementally, handle schema evolution automatically, ensure exactly-once processing, and minimize manual infrastructure management.
How should the data engineer fulfill these requirements?
How should the data engineer fulfill these requirements?
정답: D
설명: (Fast2test 회원만 볼 수 있음)
A developer has successfully configured their credentials for Databricks Repos and cloned a remote Git repository. They do not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace. Which approach allows this user to share their code updates without the risk of overwriting the work of their teammates?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
A junior developer complains that the code in their notebook isn't producing the correct results in the development environment. A shared screenshot reveals that while they're using a notebook versioned with Databricks Repos, they're using a personal branch that contains old logic. The desired branch named dev-2.3.9 is not available from the branch selection dropdown.
Which approach will allow this developer to review the current logic for this notebook?
Which approach will allow this developer to review the current logic for this notebook?
정답: E
설명: (Fast2test 회원만 볼 수 있음)
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
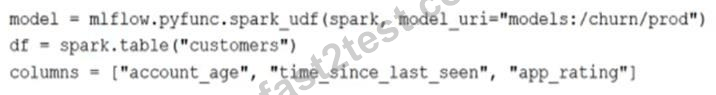
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
정답: A
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
정답: C
설명: (Fast2test 회원만 볼 수 있음)
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date. Which operation lacks support for cluster on write?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is developing a Lakeflow Declarative Pipeline (LDP) using a Databricks notebook directly connected to their pipeline. After adding new table definitions and transformation logic in their notebook, they want to check for any syntax errors in the pipeline code without actually processing data or running the pipeline. How should the data engineer perform this syntax check?
정답: A
설명: (Fast2test 회원만 볼 수 있음)
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
정답: E
설명: (Fast2test 회원만 볼 수 있음)
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table")
\
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
정답: C
설명: (Fast2test 회원만 볼 수 있음)