
Databricks Certified Associate Developer for Apache Spark 3.5 - Python - Associate-Developer-Apache-Spark-3.5무료 덤프문제 풀어보기
A data scientist is working on a large dataset in Apache Spark using PySpark. The data scientist has a DataFrame df with columns user_id, product_id, and purchase_amount and needs to perform some operations on this data efficiently.
Which sequence of operations results in transformations that require a shuffle followed by transformations that do not?
Which sequence of operations results in transformations that require a shuffle followed by transformations that do not?
정답: A
설명: (Fast2test 회원만 볼 수 있음)
A Spark developer is building an app to monitor task performance. They need to track the maximum task processing time per worker node and consolidate it on the driver for analysis.
Which technique should be used?
Which technique should be used?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
What is the benefit of Adaptive Query Execution (AQE)?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
Given a CSV file with the content:
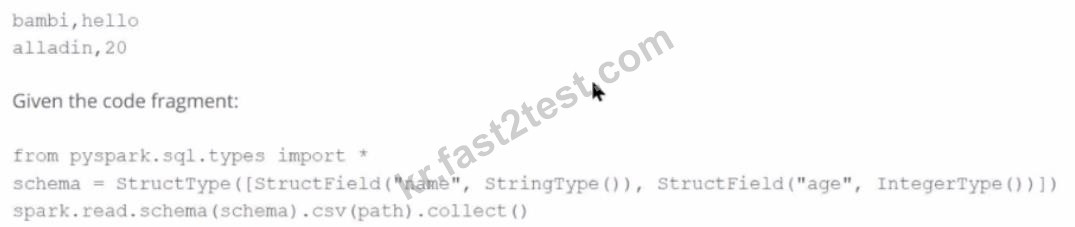
And the following code:
from pyspark.sql.types import *
schema = StructType([
StructField("name", StringType()),
StructField("age", IntegerType())
])
spark.read.schema(schema).csv(path).collect()
What is the resulting output?
And the following code:
from pyspark.sql.types import *
schema = StructType([
StructField("name", StringType()),
StructField("age", IntegerType())
])
spark.read.schema(schema).csv(path).collect()
What is the resulting output?
정답: B
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is building a Structured Streaming pipeline and wants the pipeline to recover from failures or intentional shutdowns by continuing where the pipeline left off.
How can this be achieved?
How can this be achieved?
정답: A
설명: (Fast2test 회원만 볼 수 있음)
An application architect has been investigating Spark Connect as a way to modernize existing Spark applications running in their organization.
Which requirement blocks the adoption of Spark Connect in this organization?
Which requirement blocks the adoption of Spark Connect in this organization?
정답: D
설명: (Fast2test 회원만 볼 수 있음)
A data engineer is reviewing a Spark application that applies several transformations to a DataFrame but notices that the job does not start executing immediately.
Which two characteristics of Apache Spark's execution model explain this behavior?
Choose 2 answers:
Which two characteristics of Apache Spark's execution model explain this behavior?
Choose 2 answers:
정답: A,E
설명: (Fast2test 회원만 볼 수 있음)
36 of 55.
What is the main advantage of partitioning the data when persisting tables?
What is the main advantage of partitioning the data when persisting tables?
정답: D
설명: (Fast2test 회원만 볼 수 있음)
A data engineer has been asked to produce a Parquet table which is overwritten every day with the latest data. The downstream consumer of this Parquet table has a hard requirement that the data in this table is produced with all records sorted by the market_time field.
Which line of Spark code will produce a Parquet table that meets these requirements?
Which line of Spark code will produce a Parquet table that meets these requirements?
정답: B
설명: (Fast2test 회원만 볼 수 있음)